| ||||||||||||||||||||
| ||||||||||||||||||||
New inference engine for GLM-5.3  The new version of our inference engine is so much faster that we can cut the cost of GLM-5.3 by 20%. | ||||||||||||||||||||
 | ||||||||||||||||||||
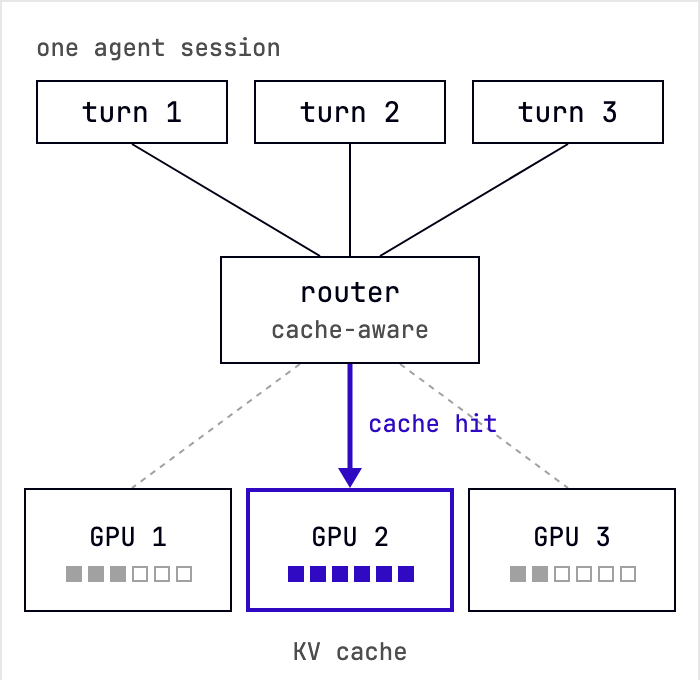
GLM-5.3 is one of our most used models, thanks to its incredible price-performance. We built custom modifications on top of NVIDIA Dynamo, NVIDIA's inference framework. The result: serverless inference with the KV-cache hit rate you would normally only see on dedicated machines. | ||||||||||||||||||||
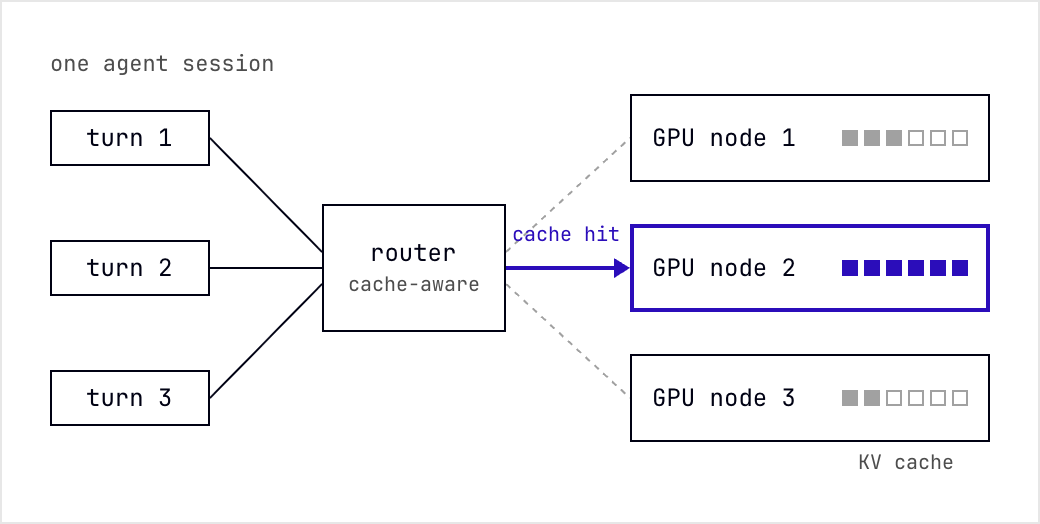 Fig. 1 Every turn of a session goes back to the GPU that already holds its KV cache, so the context isn't computed twice. | ||||||||||||||||||||
| ||||||||||||||||||||
Shoutout A huge congratulations to our rockstar team around Mina Tawfik, Aurelien Bloch and Timo Nicolai, who put in one of the most insane shifts I've ever seen to get this live.
| ||||||||||||||||||||
One more thing Go check it out on our brand-new website (best website I've ever seen, insane job Mahir). We have a new logo too, though I'm still bitter that my ChatGPT-generated logo didn't make the cut.
| ||||||||||||||||||||
Cheers, Max CTO and co-founder, Lyceum |

Oct 5, 2026
•
1 min read